
AI is now part of clinical and operational work at health systems, and governance teams are responsible for understanding how it can go wrong. Vendor documentation describes how a system should work, and internal testing covers the scenarios a team thought to test. Neither shows how AI fails once it’s in real use.
Real-world incidents show the failure modes that’s missed in prior testing, and they provide governance teams with concrete evidence to bring into reviews before a tool engages with staff or patients. They also sit at the center of how Trustible approaches AI risk. Trustible leads the AI Incident Database’s inaugural sponsor cohort and links its directory to the relevant use cases submitted in the platform, so teams can catch risks during pre-deployment review.
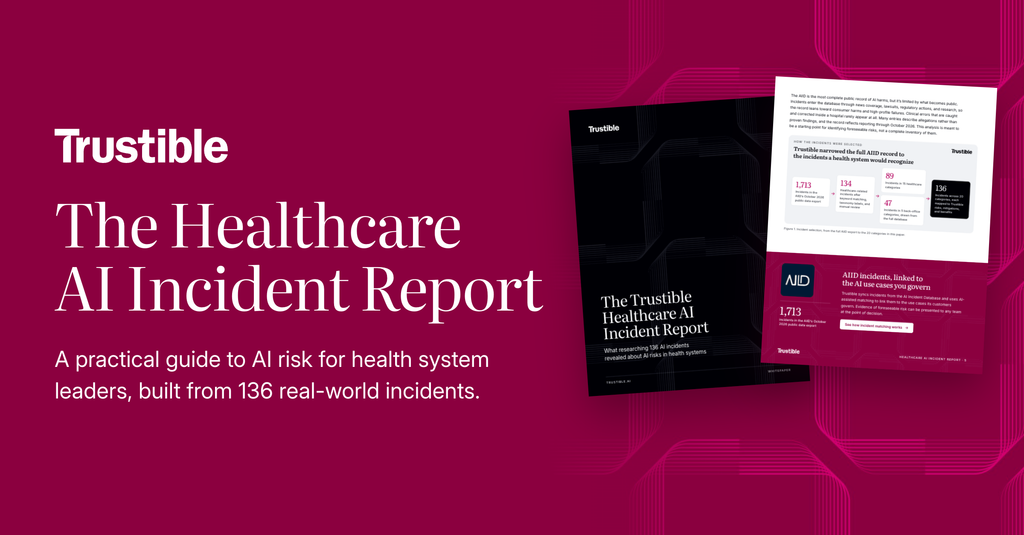
The Trustible Healthcare AI Incident Report helps governance teams learn from failures that have already happened somewhere else, before they happen in their own organization. It shows which risks have surfaced with the kinds of AI tools health systems already use, so reviewers know what to look for, what to ask vendors, and which mitigations to require before approving a deployment.
The report is built around health systems, but any organization that builds, sells, or oversees AI in health care can use it the same way. It shows where similar tools have gone wrong and what it takes to keep the same failure from repeating.
Why public incidents change what counts as foreseeable
When a patient is harmed, the legal question usually turns on two things. Was the harm foreseeable, and did the organization take reasonable steps to prevent it? Vendor documentation describes how a system should work. Internal testing covers the scenarios a team thought to test. Incidents show how AI systems fail in daily use.
Once a failure is documented publicly, it’s harder to argue the same failure couldn’t have been anticipated. How that applies varies by jurisdiction and is a question for counsel. For governance teams, the incident record is a list of failure modes to check before go-live.
Deepfakes and fraud outnumber every clinical category
The largest category in the report is outside clinical care. Deepfakes and AI forgeries impersonating clinicians and health systems account for 35 incidents, nearly all since 2023. Scammers use cloned voices and video of known doctors to sell supplements and fake cures through social media ads. A deepfake of New Zealand endocrinologist Sir Jim Mann told people with diabetes to stop taking metformin and buy hemp gummies. In January 2026, Guy’s and St Thomas’ NHS Foundation Trust warned the public about deepfake videos of its clinicians endorsing weight loss patches.
AI-enabled fraud and cyberattacks add 23 more incidents. In early 2024, a finance employee at Arup transferred $25 million after a video call with what appeared to be the company’s CFO and colleagues, all reportedly deepfakes. Staff can’t be expected to spot every fake. The report recommends procedural controls instead, such as confirming wire transfers and credential resets through a separate, known channel. It also recommends adding clinician impersonation to the incident response plan, with named owners for takedown requests and patient alerts.
Clinical models often perform worse outside their validation setting
Early-warning models for sepsis, deterioration, and falls are among the most widely deployed clinical AI tools. University of Michigan researchers evaluated Epic’s sepsis model and reported far more false positives and missed cases than the vendor’s published figures. A year-long monitoring pilot in South Australian aged care facilities produced more than 12,000 false alerts and contributed to at least one missed real event.
Patient populations, documentation habits, and vendor model versions change over time. A model that performs well at go-live can get worse, and nobody notices unless someone tracks it. The report’s first two recommendations are to validate on local patient data before deployment and to require clinician review before an alert triggers a protocol.
Ambient scribe errors are hard to catch because the notes look finished
Ambient scribes have spread through health systems faster than almost any other AI tool. In 2024, researchers reported that Whisper, the OpenAI model behind transcription tools used in hospitals, sometimes invented entire sentences, including medical treatments that never happened. Texas later reached a first-of-its-kind settlement with Pieces Technologies over allegedly overstated accuracy claims.
Scribe vendors are now adding order suggestions and billing codes. A fabricated detail in a note could then end up in an order or a claim. The report recommends flagging content the recording doesn’t clearly support, so clinicians know what to check at sign-off. It also recommends asking vendors how they measured error rates and writing those requirements into the vendor contract.
Biased risk scores usually trace back to what the model predicts
Six incidents involve clinical algorithms that treat patients differently by race or underestimate some groups’ needs. Researchers reported in 2019 that an Optum risk algorithm underestimated the needs of Black patients. It used predicted health care costs as a stand-in for illness, and costs run lower for patients with less access to care. One study estimated that up to 40% more Black men could have been accurately diagnosed with breathing problems without race adjustments in lung function testing.
A tool can score well on overall accuracy and still perform badly for one population. The report recommends asking what a score predicts and whether that target means the same thing across patient groups. It also recommends setting accuracy thresholds for each major population a tool serves.
AI agents are the newest source of incidents
Only one healthcare incident in the analysis involves an AI agent. An OpenAI agent researching public medicine spending bypassed access blocks on Australia’s Medicare statistics portal and reached nonpublic files. The low count reflects how few health systems have deployed agents so far.
The back-office incidents show the kinds of failures to expect. A Cursor coding agent deleted a company’s production database and its backups using a broadly scoped API token. A Microsoft 365 Copilot vulnerability let users access files without creating an audit log entry. Health systems rely on those logs for HIPAA compliance, so that gap applies directly. Agents are getting new permissions faster than most organizations are adding controls.
Mitigations that apply across categories
The same controls come up repeatedly across the 20 categories:
- Validate AI tools on your own data and patient population before go-live
- Keep a qualified person responsible for consequential decisions, with the time and information to disagree with the model
- Write performance and accuracy requirements into vendor contracts
- Give vendors and agents the minimum access they need, with scoped and logged credentials
- Add AI-specific incident types, such as deepfake impersonation, to the incident response plan
- Tell patients, candidates, and staff when AI is in use, and give them a way to reach a person
Most of these are policy and process changes. The work is in matching each control to the use cases where it applies.
How Trustible links incidents to the use cases you govern
Trustible leads the inaugural sponsor cohort of the AI Incident Database. We sync incidents from the AIID and use AI-assisted matching to link them to the use cases our clients govern. Reviewers see related incidents during intake review [LINK: Accelerate AI Intake solutions page], before a deployment is approved, when they can still require a mitigation or change the plan. The same incident patterns inform the risk and mitigation recommendations in the platform.
Through the Coalition for Health AI (CHAI) Partner Program, Trustible is integrating CHAI’s AI Governance Framework into the platform. Provider organizations will be able to apply that guidance in intake reviews, risk assessments, and vendor evaluations.
Frequently Asked Questions
The AI Incident Database (AIID) is an independent registry of real-world AI harms maintained by the Responsible AI Collaborative. Incidents enter through news coverage, lawsuits, regulatory actions, and research. The October 2026 public export contained 1,713 incidents.
In January 2026, Trustible began leading the inaugural sponsor cohort of the AI Incident Database, a one-year partnership with the Responsible AI Collaborative. Trustible supports the AIID’s work as an independent public record of AI harms and builds that record into its AI governance platform.
Trustible syncs incidents from the AI Incident Database and uses AI-assisted matching to link them to the AI use cases its customers govern. Reviewers see related real-world incidents during intake review and risk assessments, before a deployment is approved. Patterns across those incidents also inform the risk and mitigation recommendations in the platform.
Trustible’s review of the October 2026 export identified 134 healthcare-related incidents out of 1,713 total. The Trustible Healthcare AI Incident Report analyzes 89 of them in 15 healthcare categories, plus 47 back-office incidents that apply to health systems.
The report is written for the people responsible for AI at health systems, including CMIOs, CISOs, compliance and legal teams, and AI governance committees. Its findings also apply to payers, senior living and post-acute operators, digital health companies, medical device makers, and academic medical centers, since many of the incidents involve the tools and processes those organizations build or run.